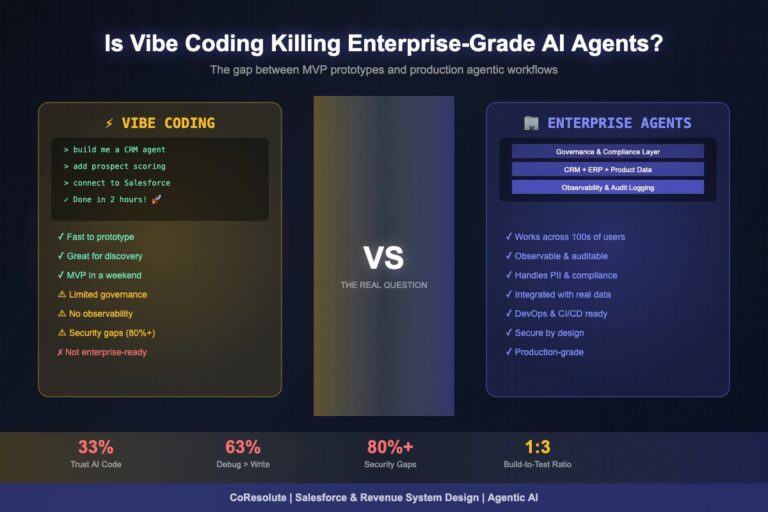
Your team is past the weekend demo. CRM logic lives in personal ChatGPT and Cursor chats. One engineer “owns” the agent. Security asks what left the building last week and nobody has a clean answer. The next buy is not another model. It is a harness: the permissions, tools, shared context, tests, and human approvals around the model that let AI do real work without becoming shadow IT.
Who this ranking is for. This list is scored for engineering and coding teams: IDE agents, CLI harnesses, cloud coding agents, and the controls that make them production-safe. If you need one platform that also covers business users (sales, ops, support, knowledge work) on equal footing with engineers, see the companion piece One harness for the whole company. Companies rarely want to run two AI stacks forever; that companion weights business and engineering criteria 50/50.
This ranking scores sixteen team and enterprise options on the rubric below and names the top ten destinations when vibe coding gets unwieldy. Prices, ratings, and limits change. Every figure below was checked on October 30, 2026. For definitions of model versus harness, and the step-by-step path into production, read the forthcoming guide From Vibe Coding to Enterprise Production (not live yet) and the thesis Enterprise Vibe Coding: When AI Code Is Production-Safe.
TL;DR
GitHub Copilot leads at 93 (Security 4, Multi-model 5) on the Business/Enterprise path we price. Cursor + Grok Bot is second at 82.
Amazon Bedrock AgentCore (Security 5), Amp, OpenAI Codex, and Claude Code tie at 80 (AgentCore wins the Security tie-break). Microsoft Foundry Agent Service is seventh at 77. Factory Droids is eighth at 75. Gemini Enterprise Agent Platform and Salesforce Agentforce tie at 70 to close the top ten (Gemini Enterprise Agent Platform leads on Multi-model).
Under the edition rule, every Security and Multi-model evidence row must sit on the Business/Team seat we price. Enterprise-only CMEK/EKM/VPC, audit APIs, and admin model allowlists are upgrade-path prose only. Same product families keep matching Security scores in the companion 50/50 ranking.
Scores assume a mid-market buyer on Business/Team editions; Enterprise editions can score higher on security and admin.
How we scored
Edition rule (editor decision, October 30, 2026). Score every tool on the Business / Team edition we price for all criteria, including Security and Multi-model access. Enterprise-only audit logs, CMEK/EKM/VPC/dedicated deploy, SSO/SCIM packaging, and Multi-model admin controls are upgrade paths only and do not count. Data rows carry an edition flag (priced / enterprise_only / not_published). Canonical Security levels are summarized in How we scored below (identical wording in the companion article). SSO and retention are recorded (or marked not published) and are not gates for levels 4-5.
SSO and retention. We record SSO and retention when sources exist (or mark them not published). They are not additional gates for Security levels 4-5.
Selection. Candidates had to be real and current in 2026, offer a team or enterprise surface, act as a harness (or coding platform with harness-like controls), and matter on the path out of unwieldy vibe coding. We started from a longer list, verified each product, cut five vibe-builder or sunset SKUs, then added Microsoft Foundry Agent Service as Azure’s managed agent counterpart to Bedrock AgentCore and Gemini Enterprise Agent Platform. Cuts kept: Windsurf (now Devin Desktop), Amazon Q Developer (end of support; successor is Kiro), Gemini Code Assist Standard/Enterprise (sunset for new buys), v0, Lovable. Selection criteria are summarized in this section.
Rubric (weights sum to 100). Revised during review on October 30, 2026 (shared security rubric with the companion article; multi-model admin-cite rule; logged in reconciliation).
| Category | Weight |
|---|---|
| Price (list seat, usage, and token/service markups) | 10 |
| Features | 15 |
| Connections (MCP, Git, CI, Slack/Teams) | 10 |
| Multi-model access (BYOK, multi-provider, local) | 10 |
| Security (SSO, SOC 2, retention, VPC/CMEK, audit logs, prompt-injection controls) | 25 |
| Team behind it (funding, company track record) | 10 |
| Ease of setup and use | 10 |
| Real user reviews (G2 product or qualifying seller profile; Reddit themes) | 10 |
Each category scores 1 to 5 against written level definitions. Total is out of 100. Ties break on Security, then Features, Connections, Multi-model, Price, Reviews, Ease, Team, then alphabetical. We never estimated missing prices, ratings, funding, or headcount. Missing published data is marked not published or could not verify. Token and service markups count in Price. G2 seller profiles count when they name a distinct product with rating and count. Prompt-injection controls must be published to support Security 4 or 5; if a vendor publishes nothing, we say not published. Sources are listed at the end. Level definitions for each weighted category are summarized in this section; we do not publish a separate methodology microsite.
External consensus. Separately, we averaged ranks from published 2025-2026 comparisons after deduplicating correlated sources. Artificial Analysis Index ranks counted once (TrueIQ kept; OnlySOTA AA column dropped). Faros runner-up ordinals that were inferred, and Windsurf->Devin remaps, are out. Method: require at least three distinct sources; primary rank is equal weight per methodology class (mean within class, then across classes); unweighted mean shown for sensitivity. Tools missing from a source are skipped, not scored as last. See the Consensus section below and the consensus table.
Combined products. Cursor and Grok Bot are scored as one entry because Grok Bot is included with Cursor paid plans and Cursor Teams and uses Cursor Cloud Agent controls under admin policy (cursor.com/docs/grok-bot, cursor.com/docs/grok-bot/teams).
Total-solution boundary. Score every SKU included in the named entry at the Business/Team edition we price. Do not import separately sold siblings. Cursor + Grok Bot includes Grok Bot because it ships with paid/Teams seats. GitHub Copilot stays alone (not Microsoft 365 Copilot or Foundry). Amazon Bedrock AgentCore is not auto-merged with Kiro or Amazon Q Developer. Gemini Enterprise Agent Platform (this list) is not the Gemini Enterprise employee front door scored in the companion.
Weight justification. Security at 25% tracks Okta’s 2026 security-buyer survey (security slows adoption; leakage and over-privilege top risks) and Forrester 2025 privacy/governance priority. Sensitivity tables for equal weights and Security ±5 live in the November 2, 2026 method notes.
Disclosure: coResolute uses Cursor and Grok Bot. We score every vendor with the same total-solution boundary, edition rule, and evidence standard. If Cursor + Grok Bot moves, it is because a surface included in the priced seat was previously scored as if it did not exist.
Data date. October 30, 2026 for score cells; method, names, and solution boundaries refreshed November 2, 2026.
How we scored this, and how others do it
Research labs and boards commonly cite task success boards (SWE-bench family, Terminal-Bench, Aider polyglot, LiveCodeBench, Artificial Analysis Coding Agent Index, HAL / arXiv 2510.11977). Cost-aware work (Kapoor et al., arXiv 2407.01502; HAL; AA efficiency metrics) adds dollars, tokens, and latency. Reliability work distinguishes pass@k (succeed once in k runs) from pass^k (succeed every run; tau-bench). Security benchmarks such as AgentDojo (arXiv 2406.13352) and InjecAgent (arXiv 2403.02691) stress prompt injection; the OWASP Top 10 for Agentic Applications for 2026 is a risk list, not a test suite. Analyst grids (Gartner, Forrester, IDC, G2) mix execution, vision, and review satisfaction, often behind paywalls.
Two pitfalls change how buyers should read IQ leaderboards. First, scaffold effects: the same model can burn up to about 40x more tokens per solved task across harnesses, with pass-rate gaps of 0-8 points, mostly not statistically distinguishable at n=50 (Scaffold Effect, arXiv 2607.22585). Second, contamination and flawed tests: OpenAI stopped reporting SWE-bench Verified for contamination and test-design issues and points buyers to SWE-bench Pro (openai.com/index/why-we-no-longer-evaluate-swe-bench-verified, checked October 30, 2026). Single-run noise is a separate reliability concern (prefer multi-attempt boards).
This ranking is a mid-market production buy of shipped harness products, not a model IQ contest. We did not run SWE-bench, AgentDojo, or pass^k ourselves. We report no cost-per-task figures; Price uses vendor list economics and published admin spend controls. Security is 25% of the score and uses the shared Security level definitions summarized above (identical wording in the companion article): level 5 needs a sourced deployment control (VPC / private networking / CMEK or equivalent / dedicated) plus SOC 2 or ISO 27001 plus audit logs plus published prompt-injection or agent-tool controls; level 4 needs PI/agent controls plus SOC 2/ISO plus audit; compliance only is max 3. Regional residency alone is not level-5 deployment. Rubric wording was revised during review and logged in reconciliation.
Supporting notes cite Kapoor et al. (arXiv 2407.01502), Scaffold Effect (arXiv 2607.22585), OpenAI SWE-bench Verified notes (link above), HAL (hal.cs.princeton.edu), tau-bench, AgentDojo, InjecAgent, and the OWASP Agentic Top 10 (links in the methods paragraph; checked October 30, 2026).
Scorecard
| Rank | Tool | Price | Features | Connections | Multi | Security | Team | Ease | Reviews | Total |
|---|---|---|---|---|---|---|---|---|---|---|
| 1 | GitHub Copilot Business / Enterprise | 5 | 5 | 5 | 5 | 4 | 5 | 5 | 4 | 93 |
| 2 | Cursor + Grok Bot (Teams / Enterprise) | 3 | 5 | 5 | 4 | 3 | 4 | 5 | 5 | 82 |
| 3 | Amazon Bedrock AgentCore | 3 | 5 | 4 | 4 | 5 | 5 | 2 | 2 | 80 |
| 4 | Amp | 5 | 4 | 4 | 4 | 4 | 3 | 4 | 4 | 80 |
| 5 | OpenAI Codex on ChatGPT Business / Enterprise | 4 | 5 | 4 | 4 | 3 | 5 | 5 | 3 | 80 |
| 6 | Claude Code on Claude Team/Enterprise | 4 | 5 | 4 | 2 | 3 | 5 | 5 | 5 | 80 |
| 7 | Microsoft Foundry Agent Service | 3 | 4 | 5 | 3 | 5 | 5 | 2 | 2 | 77 |
| 8 | Factory Droids | 3 | 5 | 4 | 4 | 4 | 4 | 3 | 2 | 75 |
| 9 | Gemini Enterprise Agent Platform | 3 | 4 | 4 | 3 | 4 | 5 | 2 | 2 | 70 |
| 10 | Salesforce Agentforce | 3 | 4 | 4 | 2 | 4 | 5 | 3 | 2 | 70 |
Tie-breaks: higher Security, then Features, Connections, Multi-model, Price, Reviews, Ease, Team, then alphabetical. At equal 80: AgentCore (Sec 5) over Amp (Sec 4) over Codex (Sec 3); Codex over Claude on Multi-model (4 vs 2). At equal 70: Gemini Enterprise Agent Platform over Agentforce on Multi-model (3 vs 2).
Consensus from other published rankings
Like a political poll average, we collected recent comparisons, removed double-counts, and averaged each tool’s rank across independent sources.
| Consensus rank | Tool | Method-weighted avg | Unweighted avg | n sources |
|---|---|---|---|---|
| 1 | Claude Code | 2.40 | 2.17 | 6 |
| 2 | Cursor + Grok Bot | 2.67 | 2.67 | 3 |
| 3 | OpenAI Codex | 2.88 | 3.20 | 5 |
| 4 | GitHub Copilot | 3.67 | 3.67 | 3 |
Method. Sources after dedup: G2 Learn Summer 2026 Grid (2026-05-08, review_grid), Zapier nine best AI coding tools (2026-03-16, editorial), Faros front-runners only (2026-10-22, editorial_forum; inferred runner-up ordinals dropped), Artificial Analysis Coding Agent Index via TrueIQ (2026-10-24, benchmark; OnlySOTA AA column dropped as the same underlying index), TensorFeed Terminal-Bench 4.0 (2026-10-28, benchmark), Tensorlake 14-day harness test (2026-08-13, hands_on). Require n >= 3 distinct sources. Primary score = equal weight per methodology class (mean of ranks within a class, then mean across classes present for that tool). Unweighted mean is sensitivity only. Missing tools are omitted from that source, not imputed as last place. No Windsurf->Devin remaps. Replit and Devin fall below n = 3 after those cleanups. Amp, Factory Droids, AgentCore, Foundry, Gemini Enterprise Agent Platform, Augment, Kiro, and Agentforce still lack enough ordinal ranks for the consensus table.
Note. Consensus remains an IQ/editorial check, not the production rubric. Sensitivity (for example Security +5 drops Cursor behind AgentCore/Amp) is documented in the November 2, 2026 method notes.
Where consensus and our rubric disagree. Claude Code still wins the public-list average because Terminal-Bench and Artificial Analysis reward agent IQ. Our rubric is a mid-market production buy: Security is 25% and requires published agent/PI controls for levels 4-5; Multi-model is its own 10%. Claude Code is officially Claude-only, so Multi-model 2 drops it to sixth on our rubric. Cursor + Grok Bot is #2 on our rubric; it still leads on BYOK on Teams, published cloud-agent mitigations, and G2 volume (Enterprise admin model allowlists and CMEK are upgrade paths; no priced data-residency row). GitHub Copilot is #1 on our rubric and fourth on the consensus table (source ranks for Cursor map to this combined entry). Raw rows live in the consensus table.
The top 10
1. GitHub Copilot Business / Enterprise (93)
What it is. This entry is GitHub Copilot alone, not Microsoft 365 Copilot or Foundry. GitHub’s coding assistant and agent stack inside the IDE and on GitHub: completions, chat, agent mode, cloud agents, code review, MCP, and org policy controls. GitHub is owned by Microsoft (Microsoft completed the acquisition on October 26, 2018; GitHub FAQ confirms ownership as of check date October 30, 2026: blogs.microsoft.com/blog/2018/10/26/microsoft-completes-github-acquisition/, github.com/frequently-asked-questions). That matters when you score the broader Microsoft family (Microsoft 365 Copilot, Foundry) against a single company-wide harness.
Best for. Teams already on GitHub Enterprise Cloud who want one seat path from inline assist to agents without changing editors, with a multi-provider model picker under admin policy.
Watch-outs. Agentic workflows can burn past included AI credits. Treat the Business pool (1,900 credits per user per month, pooled) as a baseline, not a ceiling. Admins can set budgets that allow or block additional usage. Review still belongs to humans.
Key facts (checked 2026-10-30). Copilot Business is $19 per granted seat per month with 1,900 AI credits per user per month pooled. Copilot Enterprise is $39 with 3,900 credits. Overage is $0.01 per AI credit. Supported models span OpenAI, Anthropic, Google, Microsoft, Moonshot, and xAI families (docs.github.com supported models). Business and Enterprise admins can enable or disable models and BYOK / custom model access (manage availability of default models, enable custom models, BYOK overview, configure access to AI models; checked October 30, 2026). That is Multi-model 5 (multi-provider + BYOK + admin model/key controls). Published cloud-agent risks page covers prompt-injection mitigations (risks-and-mitigations). Data residency for US/EU is real regional routing (Changelog 2026-04-13), including a noted 10% model-multiplier uplift and Gemini gaps on that changelog, but residency is not customer VPC / CMEK / dedicated single-tenant deployment under our level-5 wording. Security is 4. BYOK is first-class (bring-your-own-key); Multi-model stays 5. G2: 4.4 / 5 from 400 reviews (checked October 30, 2026 on g2.com/products/github-copilot/reviews).
2. Cursor + Grok Bot (Teams / Enterprise) (82)
What it is. One product surface for this ranking: Cursor (agentic IDE / VS Code fork with cloud agents, team rules/skills marketplace, Bugbot review, MCP, and multi-model routing) plus Grok Bot (desktop and documented iOS bots on a persistent cloud computer that can delegate repository work to Cursor Cloud Agents). Cursor and Grok Bot are scored as one entry because Grok Bot is included with Cursor paid plans and Cursor Teams and uses Cursor Cloud Agent controls under admin policy (cursor.com/docs/grok-bot, cursor.com/docs/grok-bot/teams).
Best for. Engineering teams that want the editor itself to be the harness, with shared rules, admin spend controls, BYOK, and an optional desktop agent layer that can spawn cloud coding agents.
Grok Bot and Cloud Agents (cited). Cursor docs describe Grok Bot as bots with names, jobs, and compounding context on a persistent cloud computer (browser, filesystem, terminal). Access is included with every paid individual Cursor plan and with Cursor Teams (cursor.com/docs/grok-bot; iPhone/iOS surfaces on Work with Grok Bot, checked 2026-10-30). Team admins can allow or block Bots from delegating coding tasks to Cursor Cloud Agents; the switch is on by default and delegated work runs under existing Cloud Agent controls (cursor.com/docs/grok-bot/teams). Cloud Agents run in isolated VMs with repos, dependencies, tests, MCP, and browser/computer access (cursor.com/docs/cloud-agent). The Agent SDK documents a cursor-cloud-agents extension that launches and steers those agents (cursor.com/docs/agent-sdk/guides/cloud-agents). An xAI engineering guide (2026-09-10) describes bots that create Cursor cloud agents, read transcripts, review PR proofs, and queue follow-ups (x.ai/bot/guides/grok-bot-for-engineering).
Watch-outs. On Teams, Grok Bot product enablement has no admin off switch (it is on for every member); Enterprise admins enable Grok Bot from the dashboard. Separately, Team admins can allow or block Bots from delegating work to Cursor Cloud Agents. Privacy Mode (Legacy) accounts must switch Privacy Mode before use (grok-bot/teams). Teams entry at $30 per seat is higher than Copilot Business or Claude/OpenAI Standard seats. Third-party models add API list price plus a Cursor Token Rate of $0.25 per million tokens on eligible requests. G2 and Reddit both surface credit burn and billing surprises. Enforce the monthly additional usage limit before rollout. Treat Grok Bot Cloud Agent spawning as an admin decision, not a default forever.
Key facts (checked 2026-10-30). Teams seats: Premium $30, Super $100, Ultra $200 per user per month (cursor.com/docs/account/teams/pricing). Enterprise: custom (pooled usage, SCIM, audit logs, CMEK). BYOK for OpenAI, Anthropic, Google, Azure OpenAI, and AWS Bedrock (cursor.com/help/models-and-usage/api-keys). Enterprise admins control which models and BYOK keys are available to the org (cursor.com/help/models-and-usage/api-keys). Security page: SOC 2 Type II, ISO 27001, ISO 42001. CMEK is an Enterprise upgrade path (not scored on Teams seats we price). Agent Security docs cover prompt injection, approval defaults, MCP allowlists, and limited network targets (cursor.com/docs/agent/security). No on-premises deployment today. G2: 4.6 / 5 from 331 reviews (meets Reviews level 5: 4.5+ and 200+).
Upgrade path. CMEK, Enterprise audit logs, SCIM, and Enterprise admin model/key restrictions are upgrade paths (not scored on Teams Premium seats we price).
3. Amazon Bedrock AgentCore (80)
What it is. AWS’s managed agent harness around runtime, tools, memory, identity, policy, gateway, and observability. Documented as a harness, not just a model endpoint.
Best for. Teams whose cloud standard is AWS and who need to build production agents inside their own account controls with any Bedrock or foundation model.
Watch-outs. This is a platform build, not an IDE install. Ease scores low on purpose. Published meters are clear, but dollars still require a cloud bill estimate, so Price sits at 3. G2 for AgentCore as a product page could not be verified.
Key facts (checked 2026-10-30). Runtime microVM v2 consumption: $0.1276 per vCPU-hour and $0.0169 per GB-hour. Gateway InvokeTool-style calls: $0.005 per 1,000 invocations. Pay for what you use; no separate harness seat fee published. Any foundation model / any Bedrock model documented (using-any-model). Security: dedicated microVM isolation per session, VPC connectivity, SOC 2, CloudTrail / CloudWatch audit path, and published input-validation / prompt-injection prevention guidance under the shared-responsibility model (runtime security best practices, compliance validation, VPC). That is Security 5. AgentCore scores 80.
Deployment note. VPC connectivity is a product configuration on the AgentCore path we model (not a separate higher SKU).
4. Amp (80)
What it is. Amp is an independent coding agent from Amp Frontier Corporation (spun out of Sourcegraph on December 2, 2025). CLI and web threads, hosted or self-hosted orbs, BYOK, and team sharing.
Best for. Teams that want agent horsepower without paying Amp a token markup (BYOK), multi-provider Model Routing with Allowed Models admin controls, and published prompt-injection defenses with tool/MCP permissioning.
Watch-outs. Amp does not offer a self-hosted Amp Server (security page). Self-hosted orbs are available. Enterprise is custom. Confirm orb minutes and BYOK against your security review before you standardize.
Key facts (checked 2026-10-30). Hobby free (BYOK; pay-as-you-go hosted orbs; unlimited self-hosted orbs). Individual $20 per month with 45,000 hosted orb minutes. Teams: no extra seat charge beyond member tiers; pooled credits; BYOK with no Amp token fees. Model Routing docs cover Anthropic, OpenAI, Google AI Studio, Meta AI, xAI, and OpenRouter (Amp docs, checked October 30, 2026). The No More BYOK update restored customer-managed provider keys for certain providers. Multi-model is 4 on the Teams path we price; Allowed Models admin allow/deny is an Enterprise upgrade path (required for Multi-model 5). Amp’s published security page documents a thread audit trail we score on the Teams path (distinct from Enterprise SCIM / spend-limit audit packaging).
Upgrade path. Allowed Models admin allow/deny and SCIM are Enterprise upgrade paths; Multi-model is 4 on the Teams path without priced-edition admin controls.
5. OpenAI Codex on ChatGPT Business / Enterprise (80)
What it is. OpenAI’s coding agent for plan, build, review, test, and PR prep, available through ChatGPT Business and Enterprise with CLI, IDE, desktop, and cloud surfaces.
Best for. Organizations standardizing on ChatGPT for knowledge work and wanting Codex under the same workspace admin and privacy terms, with a documented path to custom providers or local models when needed.
Watch-outs. ChatGPT Enterprise seat dollars are not published (contact sales). Score the Business list price for self-serve teams, then negotiate Enterprise for SCIM, EKM, residency, and Compliance API. Codex-specific G2 volume is still modest (20 reviews). At equal total 80, Codex beats Claude Code on Multi-model access (4 vs 2).
Key facts (checked 2026-10-30). Business Standard: $20 per user per month annual, $25 monthly. Business Premium: $100 per user per month billed annually (monthly Premium not separately confirmed on Help). Codex included on Business and Enterprise. Business: SAML SSO, SOC 2 Type 2, no training on business data by default. Enterprise adds SCIM, EKM, custom retention, Compliance API, IP allowlisting, multi-region residency. Agent approvals and security docs cover approval modes and prompt-injection / agent-tool risks (developers.openai.com/codex/agent-approvals-security). Custom providers and local models (for example Ollama / LM Studio) are documented in advanced config (developers.openai.com/codex / Codex config providers); default Business path remains OpenAI-hosted (Multi-model 4: multi-provider or BYOK path without the same first-party admin model-policy surface Copilot publishes on the Business path we price (Cursor/Amp/Factory admin model allowlists are Enterprise upgrade paths). Codex G2: 4.7 / 5 from 20 reviews. ChatGPT G2: 4.6 / 5 from about 3,800 reviews as of October 30, 2026 (context only; Codex scored on its own page; g2.com/products/chatgpt/reviews; counts drift).
Upgrade path. EKM and Compliance API / deeper audit are Enterprise upgrade paths (not scored on Business).
Sourced checks (October 30, 2026). Enterprise pricing: contact sales; credit-based and token-based options; SOC 2: SOC 2 Type 2 on Business; PI controls: Agent approvals security; audit: Codex policy/config changes recorded in workspace audit logs (Enterprise upgrade path; not scored); deployment: EKM / customer-managed keys on Enterprise only; not on Business (Enterprise upgrade path; not scored).
6. Claude Code on Claude Team/Enterprise (80)
What it is. Anthropic’s agentic coding tool in terminal, IDE, desktop, web, and Slack, sold with Claude Team and Enterprise seats that also cover Chat and Cowork.
Best for. Teams that want frontier Anthropic models plus a real coding agent under one identity, SSO, and spend controls, and who accept a Claude-only model path.
Watch-outs. Heavy multi-file agent sessions burn usage fast. Reddit and G2 both flag token burn and limit frustration. Enterprise usage is billed at API rates on top of the seat. Official docs state Anthropic does not support routing Claude Code to non-Claude models through gateways (code.claude.com/docs/en/llm-gateway). That is why Multi-model scores 2 even though Claude Code leads many public benchmark lists.
Key facts (checked 2026-10-30). Team Standard seats: $20 per member per month annual, $25 monthly. Team Premium: $100 annual, $125 monthly (Anthropic Help). Enterprise: $20 per seat per month annual (minimum 20 self-serve seats) plus usage at API rates. Claude Code included with Team seats and new/self-serve Enterprise seats. Team includes SSO and spend controls (Team plan, checked October 30, 2026). Enterprise adds SCIM, SOC 2 packaging cited on Enterprise pages, audit logs, Compliance API, and CMEK. Published security page includes a Protect against prompt injection section (permissions, network command approval, sandboxed bash, web fetch summaries). G2 for Claude Code: 4.7 / 5 from about 250 reviews as of October 30, 2026 (g2.com/products/anthropic-claude-code/reviews; counts drift).
Upgrade path. CMEK, Enterprise-cited audit/Compliance API, and SCIM packaging are upgrade paths (not scored on Team). Team SSO is priced and scored.
Sourced checks (October 30, 2026). G2: 4.7; SOC 2: SOC 2 and ISO 27001 on Enterprise (Enterprise upgrade path; not scored); PI controls: Published ‘Protect against prompt injection’ section: permissions; audit: Audit logs and Compliance API on Enterprise (Enterprise upgrade path; not scored); deployment: CMEK on Claude Enterprise only; not on Team seats we price (Enterprise upgrade path; not scored).
7. Microsoft Foundry Agent Service (77)
Naming. Foundry Agent Service (Microsoft Foundry, formerly Azure AI Foundry). Not Microsoft Copilot Studio.
What it is. Azure’s managed agent platform in Microsoft Foundry: prompt agents, hosted agents, toolboxes (including MCP), Observability, and Entra identity.
Best for. Microsoft-standard orgs that want a first-party agent runtime under Azure networking and identity, comparable to Bedrock AgentCore on AWS.
Watch-outs. This is a cloud platform path, not a drop-in coding IDE. Seat-style coding prices are not published; cost is inference, tools, and container compute. Product-specific G2 could not be verified.
Key facts (checked 2026-10-30). Prompt agents and hosted agents with managed endpoints. MCP toolboxes and Azure DevOps MCP supported. Private networking and BYO VNet for hosted agents. Microsoft Entra identity and RBAC. Prompt Shields / content-safety guardrails document user-prompt and document (indirect) prompt-injection detection (Prompt Shields, guardrails overview). Combined with customer VNet / dedicated Azure networking, Security is 5. Publishing paths include Microsoft Teams and Copilot. Pricing is consumption-based on Azure. Foundry model catalog is a hosted picker without first-party BYOK in our sources (Multi-model 3, same band as Augment).
Upgrade path. BYO VNet is a product configuration (Foundry virtual networks, checked October 30, 2026).
8. Factory Droids (75)
What it is. Factory Droids: software development agents across desktop, CLI, SDK, cloud, and local background agents, with Business and Enterprise admin controls. Product and pricing resolve on factory.com (factory.ai redirects).
Best for. Teams that want autonomous multi-step engineering agents, first-class BYOK (including local models) and a path to on-prem and dedicated compute (Enterprise admin model policy is an upgrade path).
Watch-outs. Business and Enterprise list prices are not published. Teams is $60 per month plus $40 per seat (up to 10 seats). G2 could not be verified. Validate a proof of value on one ticket type before org-wide seats.
Key facts (checked 2026-10-30). Pro $20 per month; Teams $60 + $40 per seat; Business/Enterprise custom. BYOK docs: Anthropic, OpenAI, OpenRouter, Ollama, vLLM, Groq, Gemini, Bedrock (docs.factory.ai/cli/byok/overview). BYOK on Business supports Multi-model 4; Enterprise modelPolicy / allowCustomModels admin controls (docs.factory.ai/enterprise/security) are an upgrade path and are not scored. Business: SSO, SAML/SCIM, zero data retention, audit logging. Enterprise: on-prem options, dedicated compute, data residency. Sandbox docs describe isolation and prompt-injection mitigation for agent runs (sandbox docs; compliance SOC 2 / ISO); SOC 2 Type II, ISO 27001, and ISO 42001 on Factory compliance docs. SSO, zero data retention, audit logging, published sandbox PI mitigations, and SOC 2 / ISO on the Business path we price are Security 4. Reuters reported a $200M raise at a $5B valuation (2026-09-15). Amp and Factory both score Security 4 on the priced path; Amp leads Factory on total because of Price, Reviews, and Ease (on-prem / dedicated VPC stays an Enterprise upgrade path and is not scored).
Upgrade path. On-prem / single-tenant VPC is an Enterprise upgrade path; Business scores Security 4 on SSO/ZDR/audit + PI + SOC/ISO.
9. Gemini Enterprise Agent Platform (70)
Cross-note. The company-wide Gemini Enterprise front door is scored in the companion 50/50 ranking. This entry is the Agent Platform build path.
What it is. Google’s Gemini Enterprise Agent Platform (Vertex AI / Gemini agent build path) for building and running agents on Google Cloud, with enterprise identity and Model Armor-class prompt defenses on the Gemini Enterprise path.
Best for. Teams already on Google Cloud that want agent runtime, connectors, and compliance certifications in one cloud bill.
Watch-outs. Multi-model depth is weaker than Cursor/Copilot/Amp on this rubric (Multi-model 3). CMEK on higher Gemini editions is an upgrade path relative to the Business-class path we alias from the companion.
Key facts (checked October 30, 2026).
– SOC 2: Gemini Enterprise SOC 2 among compliance certifications (source, checked October 30, 2026)
– prompt-injection controls: Model Armor PI (source, checked October 30, 2026)
– audit logs: Cloud Audit Logs for Agent Platform operations (source, checked October 30, 2026)
– multi-model: Hosted catalog (source, checked October 30, 2026)
– SSO: Google Cloud IAM / Workforce Identity for enterprise access (source, checked October 30, 2026)
– deployment: not published for Business edition CMEK; CMEK listed Standard/Plus only (source, checked October 30, 2026)
Security 4 and Multi-model 3 under the full priced-edition rule. Total 70.
Upgrade path. Higher-edition CMEK, where offered, is an upgrade path; residency alone is not level 5.
10. Salesforce Agentforce (70)
Boundary. Slack-adjacent Salesforce collaboration is in-boundary; still not a full IDE harness.
What it is. Salesforce Agentforce for CRM-native agents (sales, service, field) with Einstein Trust Layer prompt defense and org-shared Salesforce identity.
Best for. Salesforce-centric companies that want agents inside CRM rather than a separate coding-first IDE harness.
Watch-outs. Multi-model 2 on this coding rubric (Salesforce/Einstein path; broad BYOK coding not published). Not a substitute for Cursor/Copilot when the job is multi-repo engineering.
Key facts (checked October 30, 2026).
– SOC 2: SOC 2 reports for Agentforce Operations and Einstein/Agentforce on Hyperforce (source, checked October 30, 2026)
– Trust Layer / PI: Einstein Trust Layer Prompt Defense; prompt injection detection noted beta on related Help pages (source, checked October 30, 2026)
– audit: Generative AI audit / Trust Layer trails on the Agentforce path; enabling Generative AI / Trust Layer features requires Data 360 (formerly Data Cloud) to be enabled (setup, checked October 30, 2026). We do not score Shield Event Monitoring / Field Audit Trail as a priced-path requirement.
– SSO: Salesforce SSO / identity for Agentforce (source, checked October 30, 2026)
– multi-model: Agentforce on Salesforce Einstein/Hyperforce path; broad BYOK multi-provider for coding not published (source, checked October 30, 2026)
– Flex credits: $500 USD per 100k Flex Credits (source, checked October 30, 2026)
– add-on pricing: $125 user per month for unmetered employee Agentforce add-ons (Sales/Service/Field Service) (source, checked October 30, 2026)
Security 4 (PI + SOC + audit on the path we price; no customer VPC/CMEK row). Total 70.
How to choose
Start with the inventory in the forthcoming guide From Vibe Coding to Enterprise Production (not live yet): systems, permissions, data quality, shadow AI, and release path. Then match harness type to that inventory.
If GitHub is already the system of record for code, score Copilot Enterprise or Business first. If the org is standardizing on ChatGPT for knowledge work, Codex keeps identity and spend in one admin plane. If engineers live in an AI-native IDE and want BYOK plus a desktop and documented iOS bot that can spawn cloud agents, Cursor + Grok Bot is the direct upgrade from personal vibe coding. If you want Anthropic-only depth and accept that lock-in, Claude Code remains a top harness. If you must stay inside AWS or Azure control planes, AgentCore or Foundry is the harness build path (Gemini Enterprise Agent Platform is ninth at 70). If the first production agent must write to Salesforce under existing object permissions, Agentforce remains the domain fit as tenth after Security and Multi-model rescoring. Factory Droids and Amp remain inside the ten. Augment (67) and Devin (66) sit outside the ten and are strong when you want agent fleets with sharper deployment, BYOK, or autonomous cloud-engineer postures.
Pick one primary harness for the first production use case. Run a short proof of value on one real workflow with human approval gates. Promote only what survives review. Prices and ratings change; re-check vendor pricing and trust pages before you sign.
FAQ
Who is #1 on this rubric? GitHub Copilot at 93 (Security 4, Multi-model 5) on the Business/Enterprise path we price.
Why is Cursor #2 instead of #1? We price Teams Premium. Enterprise audit logs and Enterprise admin model/key controls do not count under the full edition rule, so Security is 3 and Multi-model is 4 (total 82). CMEK remains an Enterprise upgrade path.
Why do Codex and Claude score Security 3? On Business/Team seats, the audit (and for Claude, SOC packaging) rows we have are Enterprise-cited. Prompt-injection controls still count; without priced-edition SOC+audit together, the mechanical level is 3.
Do CMEK / EKM / VPC still matter? Yes, as upgrade paths. They are not scored when they exist only on Enterprise (or E5 / Purview Suite) while Price uses Business/Team seats.
Where is the business+engineering ranking? One harness for the whole company scores platforms 50/50 for business users and engineers.
How current are the prices and G2 ratings? Checked October 30, 2026 from vendor pricing or docs pages and G2 product or qualifying seller pages. If G2 could not verify a product, we recorded could not verify and did not invent a rating.
Soft next step
coResolute is a RevOps services firm that designs, builds and runs revenue systems. If you want a plain read of CRM and GTM readiness before you buy another AI seat, start with a free CRM Health Check. Contact us. No invoice. No sales pitch.
Sources
Prices, security claims, multi-model claims, and ratings change. Checked October 30, 2026 unless noted.
- Companion (business + engineering, 50/50): /one-harness-business-and-engineering/
- Thoughtworks on AI agent harnesses: https://www.thoughtworks.com/en-us/insights/blog/machine-learning-and-ai/ai-agent-harness
- coResolute thesis: https://coresolute.com/vibe-coding-enterprise-grade-ai-agents/
- Companion guide (proposed): /from-vibe-coding-to-enterprise-production/
- Claude Team plan: https://support.claude.com/en/articles/9266767-what-is-the-team-plan
- Claude Code on Team/Enterprise: https://support.claude.com/en/articles/11845131-use-claude-code-with-your-team-or-enterprise-plan
- Claude Enterprise: https://claude.com/solutions/enterprise
- Claude Code security (incl. prompt injection): https://code.claude.com/docs/en/security
- Claude Code LLM gateway (non-Claude unsupported): https://code.claude.com/docs/en/llm-gateway
- ChatGPT Business overview: https://help.openai.com/en/articles/8792828-chatgpt-business-overview
- OpenAI business pricing: https://openai.com/business/pricing/
- Codex enterprise: https://chatgpt.com/codex/enterprise/
- Microsoft completes GitHub acquisition (2018-10-26): https://blogs.microsoft.com/blog/2018/10/26/microsoft-completes-github-acquisition/
- GitHub FAQ (Is GitHub owned by Microsoft?): https://github.com/frequently-asked-questions
- GitHub Copilot plans: https://docs.github.com/en/copilot/get-started/plans
- GitHub Copilot billing budgets: https://docs.github.com/en/copilot/concepts/billing-and-usage/organizations-and-enterprises/billing
- GitHub Copilot supported models: https://docs.github.com/en/copilot/reference/ai-models/supported-models
- GitHub Copilot cloud agent risks/mitigations: https://docs.github.com/en/copilot/concepts/security-governance-and-network-settings/risks-and-mitigations
- Cursor Teams pricing: https://cursor.com/docs/account/teams/pricing
- Cursor security: https://cursor.com/security
- Cursor enterprise: https://cursor.com/enterprise
- Cursor BYOK: https://cursor.com/help/models-and-usage/api-keys
- Cursor models and pricing: https://cursor.com/docs/models-and-pricing
- Cursor Agent Security: https://cursor.com/docs/agent/security
- Cursor Grok Bot: https://cursor.com/docs/grok-bot
- Cursor Grok Bot Teams: https://cursor.com/docs/grok-bot/teams
- Cursor Cloud Agents: https://cursor.com/docs/cloud-agent
- Cursor Agent SDK cloud agents: https://cursor.com/docs/agent-sdk/guides/cloud-agents
- xAI Grok Bot for Engineering (2026-09-10): https://x.ai/bot/guides/grok-bot-for-engineering
- Devin pricing: https://devin.ai/pricing
- Devin Desktop / Windsurf FAQ: https://docs.devin.ai/desktop/devin-desktop-faq
- Replit Enterprise: https://docs.replit.com/billing/plans/replit-enterprise
- Bolt pricing: https://bolt.new/pricing
- Bedrock AgentCore pricing: https://aws.amazon.com/bedrock/agentcore/pricing/
- Bedrock AgentCore harness docs: https://docs.aws.amazon.com/bedrock-agentcore/latest/devguide/harness.html
- Bedrock AgentCore any model: https://docs.aws.amazon.com/bedrock-agentcore/latest/devguide/using-any-model.html
- Microsoft Foundry Agent Service overview: https://learn.microsoft.com/en-us/azure/ai-foundry/agents/overview
- Kiro pricing: https://kiro.dev/pricing/
- Amazon Q Developer end of support: https://aws.amazon.com/blogs/devops/amazon-q-developer-end-of-support-announcement/
- Gemini Enterprise Agent Platform pricing: https://cloud.google.com/products/gemini-enterprise-agent-platform/pricing
- Gemini Code Assist sunset: https://docs.cloud.google.com/gemini/docs/codeassist/sunset
- Salesforce Agentforce pricing: https://www.salesforce.com/agentforce/pricing/
- Salesforce Agentforce SOC 2 (compliance site): https://compliance.salesforce.com/en/documents/a00Kd00000zh1D6IAI
- Amp pricing: https://ampcode.com/pricing
- Amp security (incl. prompt injection): https://ampcode.com/security
- Amp Model Routing: https://ampcode.com/docs/customize/model-routing
- Amp Frontier Corporation: https://ampcode.com/news/amp-frontier-corporation
- Amp spin-out from Sourcegraph: https://sourcegraph.com/blog/why-sourcegraph-and-amp-are-becoming-independent-companies
- Augment pricing: https://www.augmentcode.com/pricing
- Augment available models: https://docs.augmentcode.com/models/available-models
- Factory pricing: https://www.factory.com/pricing
- Factory BYOK: https://docs.factory.com/model-independence/byok
- Factory enterprise: https://www.factory.ai/enterprise
- GitHub Copilot BYOK / manage AI models: https://docs.github.com/en/copilot/how-tos/administer-copilot/manage-for-enterprise/manage-availability-of-default-models
- GitHub Copilot data residency changelog: https://github.blog/changelog/2026-04-13-copilot-data-residency-in-us-eu-and-fedramp-compliance-now-available/
- Codex agent approvals / security: https://developers.openai.com/codex/agent-approvals-security
- Codex config advanced / providers: https://developers.openai.com/codex/
- Factory sandbox / SOC docs: https://docs.factory.com
- Bedrock AgentCore security best practices: https://docs.aws.amazon.com/bedrock-agentcore/latest/devguide/runtime-security-best-practices.html
- Bedrock AgentCore compliance: https://docs.aws.amazon.com/bedrock-agentcore/latest/devguide/compliance-validation.html
- Bedrock AgentCore VPC: https://docs.aws.amazon.com/bedrock-agentcore/latest/devguide/agentcore-vpc.html
- Foundry Prompt Shields: https://learn.microsoft.com/en-us/azure/foundry/openai/concepts/content-filter-prompt-shields
- Foundry guardrails: https://learn.microsoft.com/en-us/azure/foundry/guardrails/guardrails-overview
- Devin CLI sandbox: https://docs.devin.ai/cli/sandbox
- Devin enterprise VPC: https://docs.devin.ai/enterprise/vpc/overview
- Amp Allowed Models (admin): ampcode.com/docs/enterprise/allowed-models
- Reuters Factory $5B valuation: https://www.reuters.com/business/ai-coding-agent-startup-factory-triples-valuation-5-billion-latest-funding-round-2026-09-15/
- G2 Claude Code: https://www.g2.com/products/anthropic-claude-code/reviews
- G2 Codex: https://www.g2.com/products/openai-codex/reviews
- G2 ChatGPT: https://www.g2.com/products/chatgpt/reviews
- G2 GitHub Copilot: https://www.g2.com/products/github-copilot/reviews
- G2 Cursor: https://www.g2.com/products/cursor/reviews
- G2 Replit: https://www.g2.com/products/replit/reviews
- G2 Amp seller: https://www.g2.com/sellers/amp-code
- G2 Tabnine: https://www.g2.com/products/tabnine/reviews
- G2 Learn best AI coding assistants: https://learn.g2.com/best-ai-coding-assistants
- Zapier best AI coding tools: https://zapier.com/blog/ai-coding-tools/
- Faros best AI coding agents 2026: https://www.faros.ai/blog/best-ai-coding-agents-2026
- TrueIQ coding agent benchmark rankings: https://trueiq.si/guides/coding-agent-benchmark-rankings
- TensorFeed harnesses: https://tensorfeed.ai/harnesses
- OnlySOTA harnesses: https://onlysota.ai/harnesses
- Tensorlake best AI coding agents 2026: https://www.tensorlake.ai/blog/best-ai-coding-agents-2026
- Tabnine / Tricentis acquisition: https://www.tabnine.com/blog/a-new-chapter-for-tabnine/
- Reuters Anthropic valuation: https://www.reuters.com/business/anthropic-raises-65-billion-now-valued-965-billion-2026-05-28/
- Reuters Cognition valuation: https://www.reuters.com/technology/cognition-ai-raises-2-billion-48-billion-valuation-2026-09-08/
- Reddit Claude Code vs Copilot limits: https://www.reddit.com/r/GithubCopilot/comments/1rttkzw/claude_code_vs_github_copilot_limits/
- Reddit company vs individual AI tools: https://www.reddit.com/r/ChatGPTCoding/comments/1rx4838/ai_dev_tools_for_companies_vs_individual_devs_are/
- Reddit Cursor limits: https://www.reddit.com/r/cursor/comments/1sm08k7/current_cursor_pro_limits_vs_standalone_claude/
- https://learn.microsoft.com/en-us/azure/foundry/agents/how-to/virtual-networks
- https://github.com/features/copilot
Why didn’t you merge Microsoft or AWS into one score? Separately sold siblings stay separate unless the entry name combines them. GitHub Copilot is not Microsoft 365 Copilot or Foundry. AgentCore is not Kiro or Amazon Q Developer. Same total-solution rule for every vendor.